
Agentic Readiness
What the Agentic Readiness audit checks on your website, how the level and score work, and how to allowlist our scanner.
AI agents do more than read a page. They look for machine-readable signals that tell them what a site allows, where its content lives in a clean format, and whether it offers tools or APIs they can call. The Agentic Readiness audit checks your website for those signals and tells you which ones are missing, in the order that matters.
Open Agentic Readiness in your project to run an audit. Each report gives you a level from 0 to 5, a score from 0 to 100, and a result for every check with guidance on how to fix what failed.
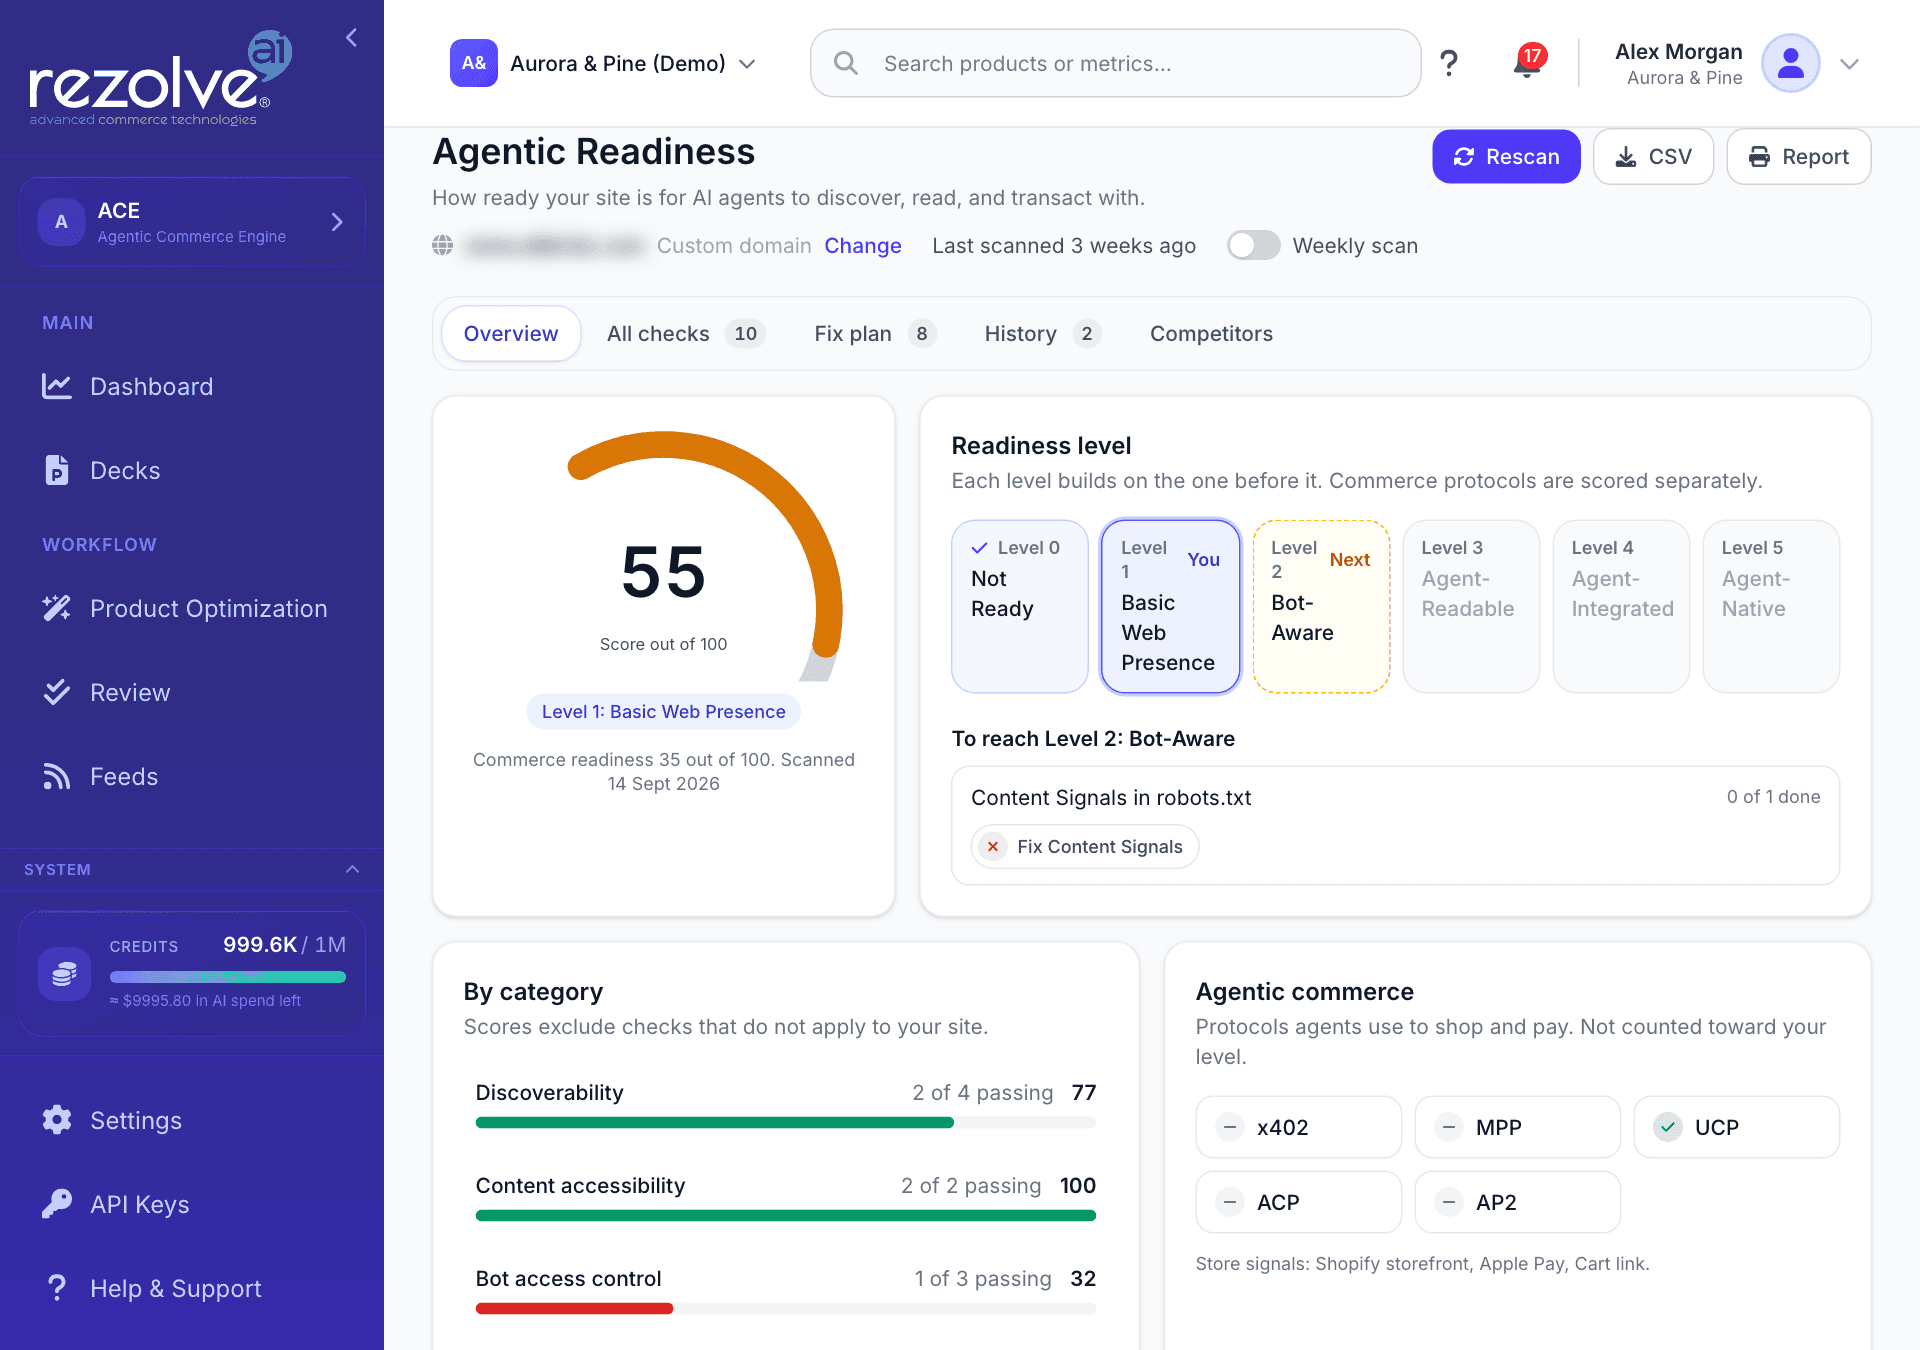
The audit looks at your website. To check how complete your product feed is for AI shopping agents, open the Catalog feed readiness for AI agents card on the Optimize page.
What the audit checks
Checks are grouped into six categories. Every check reports one of four results: pass, fail, not applicable (the check does not apply to your site), or could not check (we could not reach the resource, for example because a firewall blocked the request, the request timed out, or your server returned an error).
Discoverability
Can an agent find its way around your site?
| Check | What we look for |
|---|---|
| robots.txt | A valid robots.txt at the root of your domain. |
| Sitemap | An XML sitemap, either declared in robots.txt or at a standard location. |
| Link headers | HTTP Link headers on your homepage that point agents at related resources. |
| DNS for AI Discovery | _agents DNS records that advertise agent resources for your domain. |
Content
Can an agent read your content without parsing a full web page?
| Check | What we look for |
|---|---|
| Markdown negotiation | Your pages return Markdown when a request asks for text/markdown. |
| llms.txt | An /llms.txt file that summarises your site for language models. |
Bot access
Have you said what AI bots may do?
| Check | What we look for |
|---|---|
| AI bot rules | robots.txt rules that name AI crawlers and agents explicitly. |
| Content Signals | Content Signals in robots.txt stating how your content may be used, for example for search or for training. |
| Web Bot Auth | A key directory at /.well-known/http-message-signatures-directory that publishes the keys used to sign automated requests. |
The crawler table in AI bot rules also lists Muse (reported), the muse token that Cloudflare Radar reports for Meta's personal agent (October 2026). Meta has not confirmed the token, so the row shows what your robots.txt says to it but never earns or costs credit, and a change to it never raises an alert.
API, auth and MCP
Can an agent do something on your site, not just read it?
| Check | What we look for |
|---|---|
| API Catalog | A /.well-known/api-catalog document listing your public APIs. |
| OAuth discovery | OAuth authorization server metadata. |
| OAuth Protected Resource | Protected resource metadata that tells agents how to authenticate. |
| auth.md | An /auth.md file describing how agents should authenticate. |
| MCP Server Card | A card describing your Model Context Protocol server. |
| A2A Agent Card | An Agent2Agent card describing an agent you host. |
| Agent Skills | A published index of skills agents can use with your site. |
| WebMCP | Tools your pages expose to agents running in the browser. |
| ARD manifest | An agent resource discovery manifest. |
Commerce
Can an agent buy from you? These checks cover agentic payment and checkout protocols: x402, MPP, UCP, ACP and AP2. They are reported separately and do not count toward your level, because many sites that are fully ready for agents do not sell anything.
| Check | What we look for |
|---|---|
| x402 | An HTTP 402 answer with x402 payment requirements on /, /api or /api/v1. |
| MPP | Operations priced with x-payment-info in your /openapi.json. |
| UCP | A Universal Commerce Protocol profile at /.well-known/ucp. |
| ACP | An Agentic Commerce Protocol discovery document at /.well-known/acp.json. |
| AP2 | The Agent Payments Protocol extension on your A2A Agent Card. |
If your site is a store, a protocol that is missing shows as Not found and counts against your commerce score. We treat a site as a store when we find a known store platform, or any two signs of one: add to cart or basket buttons, cart, basket or checkout links, prices, product markup, checkout pages listed in robots.txt, a product sitemap, or a product catalog in your project.
Personal agents
Can an agent that acts for one person reach your site, your tools and your sign in? These checks are reported separately and count toward neither your level nor your score. The Shopping agents tab reads them together.
| Check | What we look for |
|---|---|
| Personal Agent Protocol | A /.well-known/poppy.json document (draft 0.2, October 2026) that names this domain and at least one route: your own agent, your APIs or a browser session. We also check the sign in issuer's metadata, that each MCP API names that issuer, and that your agent asks a caller without credentials to sign in. Adoption is early, so most sites have none yet. |
| MCP tools | The MCP servers we find (from your MCP Server Card, ARD manifest or poppy.json, and on a Shopify store the /api/mcp and /api/ucp/mcp endpoints Shopify runs) answer a handshake and list the tools an agent could use. A server that asks agents to sign in should say where. |
| Cloud browser | A headless browser running in a data centre, as cloud agents browse, reaches your homepage without a firewall page. If our scanner was turned away, the browser visit goes through a residential connection instead, and this shows as could not check. |
| Business contact | An email address whose domain has mail servers, and a phone number, in your homepage's Organization structured data or on your contact page. Some personal agents write to or ring a business for the shopper, and they look in those two places. Details only in page links earn partial credit. |
Accessibility for agents
Can an agent tell what each button, link and field on your homepage is for? Agents read a page the way screen readers do, so this check also counts toward neither your level nor your score. Failing it puts a fix under Accessibility for agents on the Fix plan tab.
| Check | What we look for |
|---|---|
| Controls agents can read | Every button, link and field on your homepage that an agent could reach has a name and a role it can read: no Buttons with no name or Links with no name, no Fields with no label or Fields labelled only by a placeholder, and no Search boxes that do not say they are one. Read in the same browser visit as WebMCP, so it adds no request. The check lists each control with the WCAG success criterion it breaks. |
Levels
The level tells you which rung of the ladder you are on. Each level needs everything the level below it needs, plus more.
| Level | Name | What it needs |
|---|---|---|
| 0 | Not Ready | Fewer than two of the level 1 signals. |
| 1 | Basic Web Presence | Two of: robots.txt, a sitemap, Link headers. |
| 2 | Bot-Aware | Level 1, plus AI bot rules and Content Signals in robots.txt. |
| 3 | Agent-Readable | Level 2, plus Markdown negotiation. |
| 4 | Agent-Integrated | Level 3, plus at least one of: MCP Server Card, A2A Agent Card, Agent Skills, API Catalog. |
| 5 | Agent-Native | Level 4, plus at least two of: Web Bot Auth; all four of the level 4 integrations; auth metadata (OAuth discovery, OAuth Protected Resource or auth.md). |
The report shows exactly which checks stand between you and the next level.
Score
The score, from 0 to 100, says how far along the whole ladder you are. Unlike the level, it also counts checks that no level requires, such as llms.txt, WebMCP, the ARD manifest and DNS for AI Discovery.
- A pass earns the check's weight. A fail earns nothing.
- Not applicable checks are left out entirely, so they never lower your score.
- Personal agents and Accessibility for agents checks are never in the score, and commerce checks have a score of their own.
- Could not check results are also left out of the score, but they lower its coverage. When too little of your site could be checked, the score is marked provisional: it is based on what we could see, not a verdict on what we could not.
A site behind a strict firewall therefore gets a provisional score rather than a falsely low one. See Our scanner to let the audit through.
Shopping agents
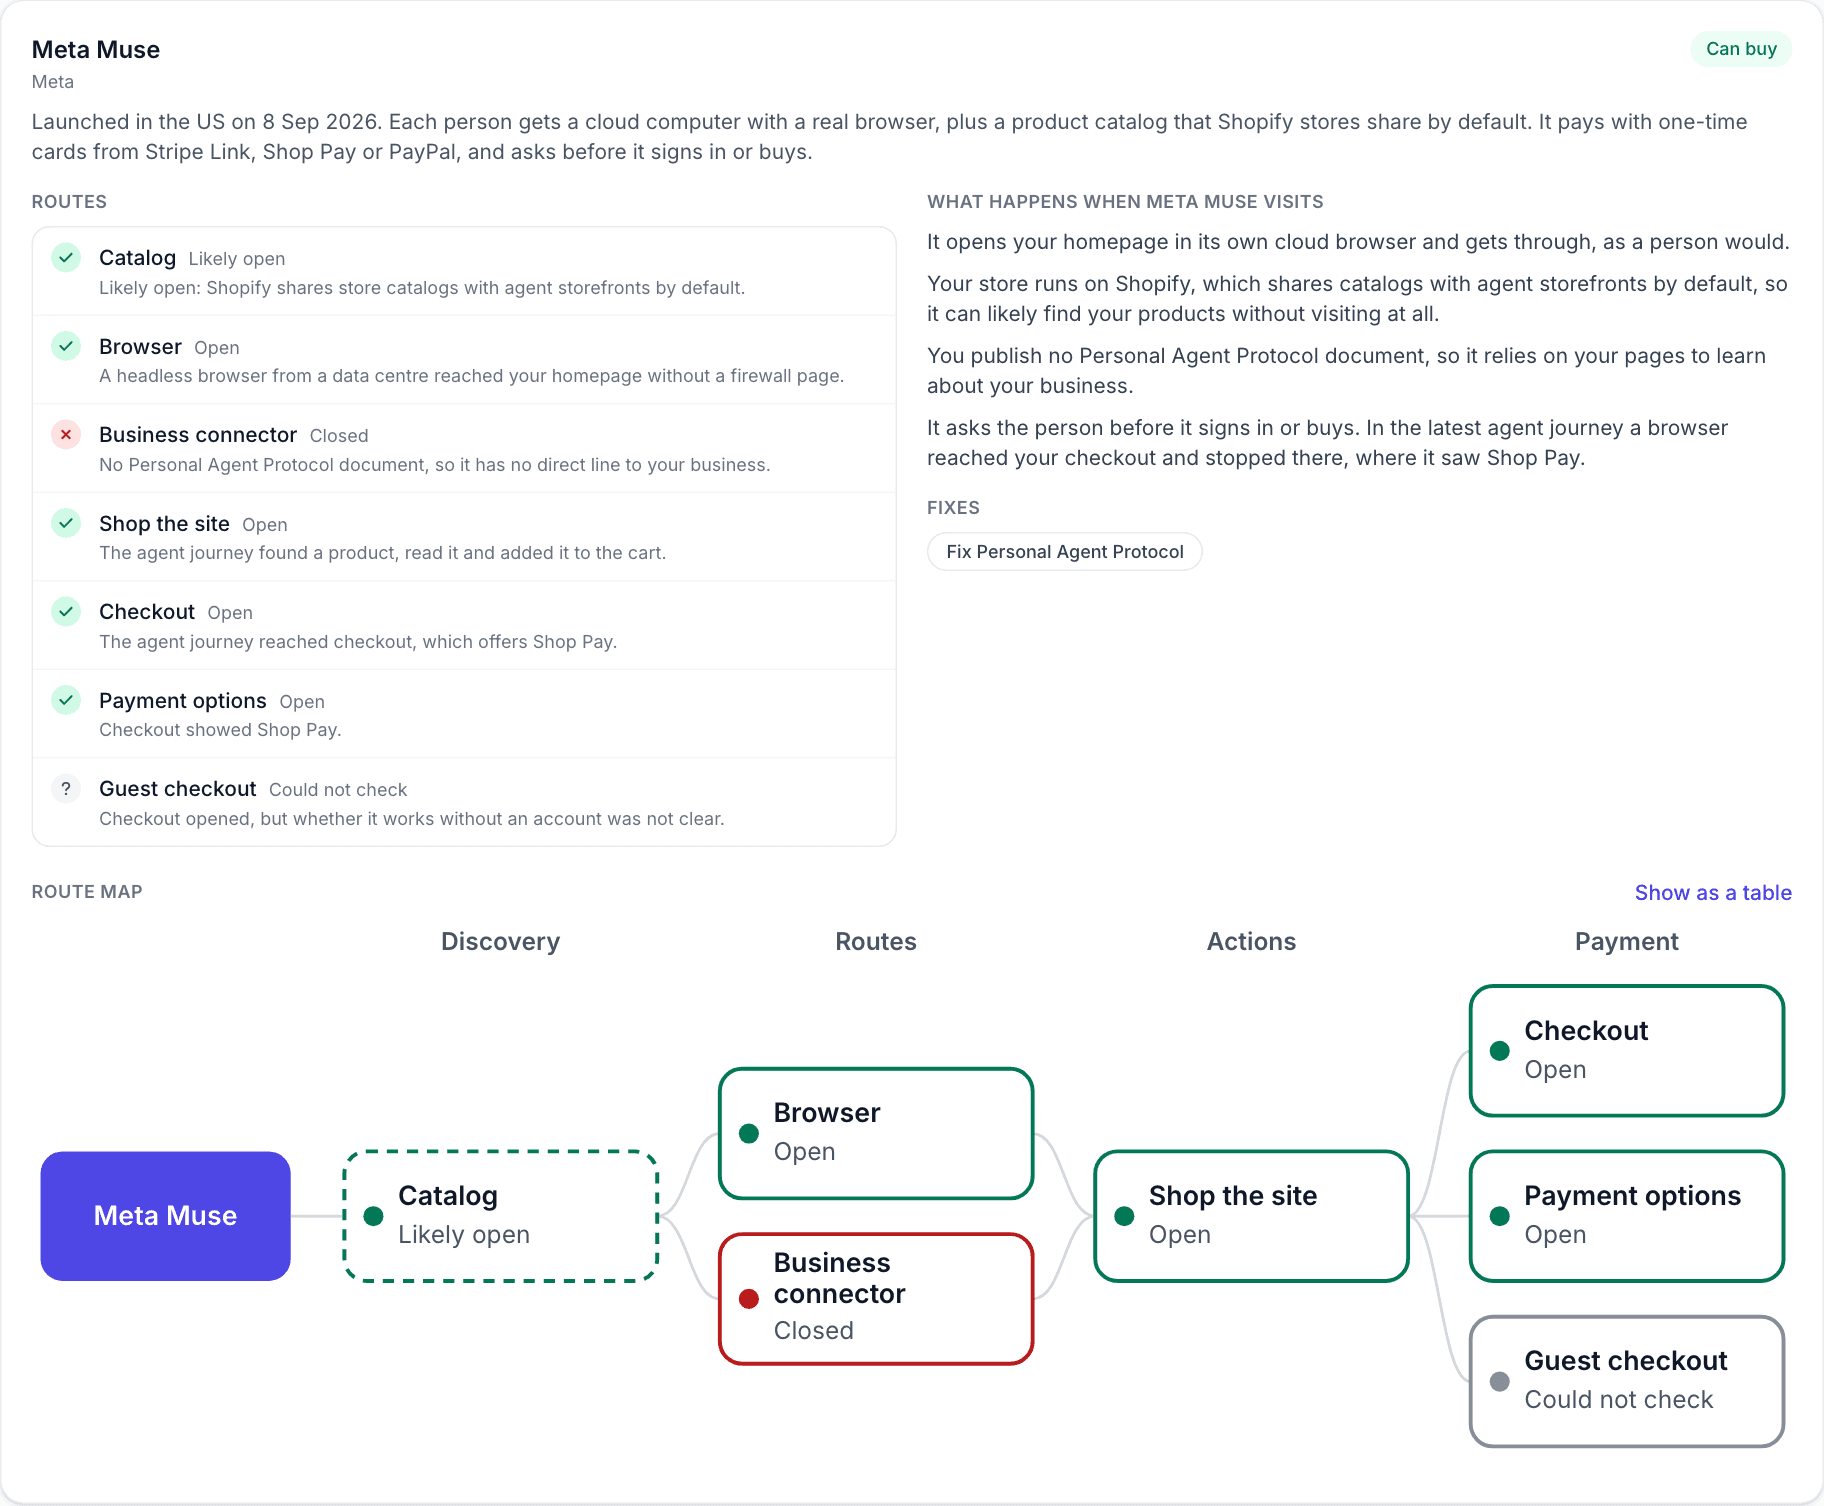
The Shopping agents tab shows how four personal agents would get on with your site, read from your latest scan, your latest agent journey and your latest Agent shelf run: Meta Muse, OpenAI Dots, Instinct and an agent using the Personal Agent Protocol. Each card shows:
- A verdict: Can buy, Can browse, buys at your retailers, Can browse, buying not confirmed, No way in or Not measured. It rests only on what the scan measured. A route we infer, such as a catalog that Shopify shares with agent storefronts by default, shows as Likely open and never raises the verdict.
- Routes: each way the agent could get in, such as its browser, your MCP plugin, an agentic checkout document or your own agent, marked Open, Partly open, Closed, Could not check or Not measured. Routes that only a walk through your site to checkout can measure, such as paying at checkout, show as Not measured until you run an agent journey (below).
- What happens when it visits, in a few plain sentences.
- Fixes: each opens the check behind a route, with its fix.
- A route map from discovery to payment. Select Show as a table for the same routes as a table.
Instinct shops differently from the other two, and its card follows how it works. It searches the Shopify merchant network before it opens your site, so its Shopify network route is measured by the Agent shelf, where shopper agents search your own catalogue. It pays with a fast wallet checkout or a one-time card for an amount the person approves, so Total before paying asks whether the price and the delivery cost were readable before checkout. It keeps the person's saved logins, so a checkout that asks to sign in is partly open rather than closed. And it writes to and rings businesses, so Email and phone reads the Business contact check.
The facts about Meta Muse, OpenAI Dots and the Personal Agent Protocol were checked on 24 October 2026, and about Instinct on 10 November 2026. These products change quickly, so the card for each one says when it launched.
Shopping agents and the agent journey
Personal shopping agents browse your store in a real browser running on a cloud computer. The scan cannot tell whether one of them gets from your homepage to your checkout, so the Shopping agents tab can send a real browser through your site to find out. This is the agent journey.
What it does
Select Run an agent journey on the Shopping agents tab, choose What to test and where to Start from, then select Start journey. With Any product to checkout you can type a Product to look for (optional); if you leave it empty, the journey looks for a product from your catalog. The journey:
- Opens your homepage, from a data centre, as shopping agents do.
- Rejects the cookie banner (or picks necessary cookies only), confirms an age check that asks with a single button, as a shopper of legal age would, and closes newsletter popups. An age check that asks for a date of birth is never filled in.
- Searches for the product, opens it, and reads its price, stock, delivery and returns information.
- Picks the first available option, such as a size, and adds the product to the cart.
- Opens checkout and stops as soon as checkout appears, reading the payment options shown without clicking anything.
What to test
Shoppers rarely type a product's full catalog name, so What to test asks the journey for something more specific, and judges the result against it:
- Any product to checkout: the journey above. It passes when it reaches checkout.
- A kind of product: the words a shopper would search for, such as double mattress firm or 65 inch OLED TV. It passes when it reaches a product whose name carries most of those words. Sizes written as 65 inch, 65" or 65in count as the same.
- A kind of product from a brand: a brand and the words, such as Samsung and OLED TV. It passes on that brand's product.
- Do you stock a brand?: the journey looks for the brand on your site and answers yes or no, quoting the words on the page that show it. It never adds to the cart.
- Answer a shopper's question: the journey looks for the answer to a question shoppers ask (your Returns policy, Delivery cost and time, Warranty, Loyalty scheme, or Collecting in store) on your policy and help pages, footer links and product pages, and answers with a sentence and the words on the page that show it. It never adds to the cart.
- Ask your support chat: the journey opens your site's chat, types one question and sends it: your Returns policy, Delivery cost and time, Warranty, Loyalty scheme, Collecting in store, or Stock of a product, with the Product to ask about. It records how long the chat took to reply and whether it handed over to a person, then checks the answer on your own policy page or product page. It passes when the chat answers and your page does not say otherwise. It types only that question into the chat, never a name, an email or anything else, even when the chat asks for them, and a chat that wants those first fails with The chat asked for personal details first. It reads chats from Intercom, Zendesk, Gorgias, LivePerson, Ada, Tidio, Drift and Salesforce, and chats drawn on the page itself.
- Find a product from its image: give the Product name and the Address of the product's image from your catalog. Where your site lets shoppers search by image, the journey uploads that image through your search by image button or field and passes when it reaches that product. The image is the only file it ever uploads, fetched by us from the address you gave, and only into a control for searching by image. If your site has no way to search by image, the result says Your site has no way to search by image.
- Click and collect: give the Postcode of one of your stores. The journey finds a product, looks for click and collect on its page or in the cart, and types that postcode into a store finder if it asks for one. It passes when your site shows collection is offered for the product. The postcode is the only thing it types outside a search box, and only into a postcode or store finder field.
- Check out as a guest: the journey buys any product to checkout and passes when checkout offers to continue without an account. As always, it types nothing at checkout and stops there.
- One product by name, One product by barcode (GTIN) and One product by part number (MPN): it passes when it reaches that exact product, matched by its address, the identifier in its product data or on the page, or most of its name. A barcode is typed into your search box as it is, the one long number the journey types.
Start from can be Your homepage, A collection page, A product page or An article or guide, as when a shopper arrives from an answer that linked to it. Give the page's address; it must be on your own site.
The result says Passed or Did not pass, how far the journey got, and when it did not pass, one reason, such as Could not find a matching product or Found products, but not the one asked for, with whether it lay with your site, your bot protection or the journey's own rules, which team usually fixes it, and how.
Some sites show their products but sell them only through retailers, with no price, cart or checkout of their own, as many brand sites do. The journey recognises one on the first product page it opens. It looks once more, on your own where to buy page when the product page links to one, or further down the product page, then records the retailers your pages link to and stops with Found your products, no shop on this site. The tab then shows Where shoppers buy in place of checkout: the retailers, where they were found, whether a where to buy box from another site hides them, and whether your product data names them. The shopping agent cards read Can browse, buys at your retailers when the journey could read where to buy.
A browsing model decides each step, and every step is checked by fixed rules before the browser acts. An action that changed nothing twice is refused, and the journey stops if the model keeps choosing such actions, so it does not spend credits going round in circles. In the same way, if the model asks three times for a step the rules refuse, the journey stops with Stopped at a step the journey will not take. That is a limit of the test rather than something on your site, so it is not listed under what got in the way and it does not count against the shopping agent routes. Each step is recorded with what the browser did, why, the page it was on and a screenshot. Open Every step, with screenshots to read them. Select Stop journey to stop one that is running.
The result fills in the routes the scan could not measure: whether an agent can shop your site, whether it reaches checkout, the payment options checkout shows and whether a guest can check out. A checkout route counts as open only when a journey actually reached your checkout. The tab also lists what got in the way, such as a challenge page, a forced sign in or a disabled add to cart button, each with its fix. Once you have run two journeys, a chart shows how far each one got.
Does every reader see the same product?
When a journey tests a product page, it then checks whether that page tells everyone the same thing. It reads the page five ways and lines up the name, brand, price, stock, barcode, rating and review count:
- Structured data: the product data in the page as your site serves it, before any script runs. Crawlers and most agents read this first.
- Page before scripts: the words of the page as served, which is all that a crawler that does not run scripts reads.
- Page as shown: what a shopper sees once the page has loaded.
- What the agent noted: what the journey wrote down from the page.
- Your catalog: the product in your own catalog, matched by its address or barcode.
Each detail reads Agree, Differ or Missing somewhere, with the likely cause, such as a price in your structured data that is out of date, or stock that only appears once scripts run. The page is fetched once as a browser and once as our scanner, which names itself as a bot. If the two differ in price, stock or name, the table says so, because agents may then be told something shoppers are not. This check calls no model and uses no credits.
When a suite completes, the same check runs on up to ten product pages from your catalog that link to your site, spread across your categories, so it covers products no journey reached. Without a browser it compares three readers: your structured data, the page before scripts run, and your catalog. The results show under Product pages from your catalog on the suite, with the pages that disagree first. It also calls no model and uses no credits.
Accessibility for agents on a journey
Agents read a page the way screen readers do: through the names, roles and labels in its markup. On every page a journey visits, it lists the controls an agent cannot read properly, with the WCAG success criterion each one breaks and how to fix it:
- Buttons with no name and Links with no name, such as an icon button for search or the basket with no text and no aria-label.
- Fields with no label, and Fields labelled only by a placeholder, which loses its meaning once something is typed.
- Search boxes that do not say they are one, which an agent has to guess at.
A control the agent tried to use is marked The agent used it, since that one got in its way. Each of these is an accessibility issue for people too. The check covers the controls on the pages the journey visited, not your whole site; the audit's Controls agents can read check covers your homepage on every scan.
Test scenarios and suites
One journey is one try. The model that drives the browser and your site both vary from run to run, so one pass or one fail says little on its own. The Test scenarios tab keeps the scenarios that matter to you and runs them together, five times each, as a suite.
- Suggest scenarios from my catalog reads your catalog and offers up to ten to start with: a kind of product you sell, one of your brands' products, whether you stock that brand, one product by name, barcode and part number, a start on one of your product pages, your returns policy, and checking out as a guest. Tick the ones to keep. Add a scenario saves one of your own.
- Run all runs every scenario switched on under In Run all, five times each, after telling you how many journeys that is and roughly how many credits it usually uses. Run this one runs a single scenario again, for checking a fix. Every week runs the suite once a week, billed to whoever switched it on.
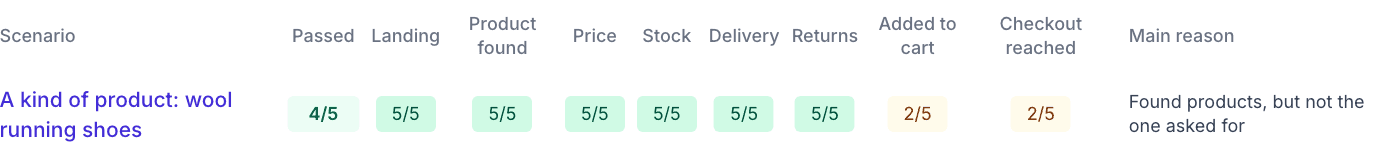
- Each scenario shows how many of its runs passed in the latest suite, its main reason when most failed, and a line of its pass rate over past suites.
- Under Suites, pick a suite to see a grid of every scenario against every stage, how many runs passed and got that far, and the main reason. What changed since the last suite lists the scenarios that now pass or now fail. Why runs failed, and who fixes it groups the reasons by the team that usually fixes them, with each fix. Download CSV gives a row per run, to share with your developers.
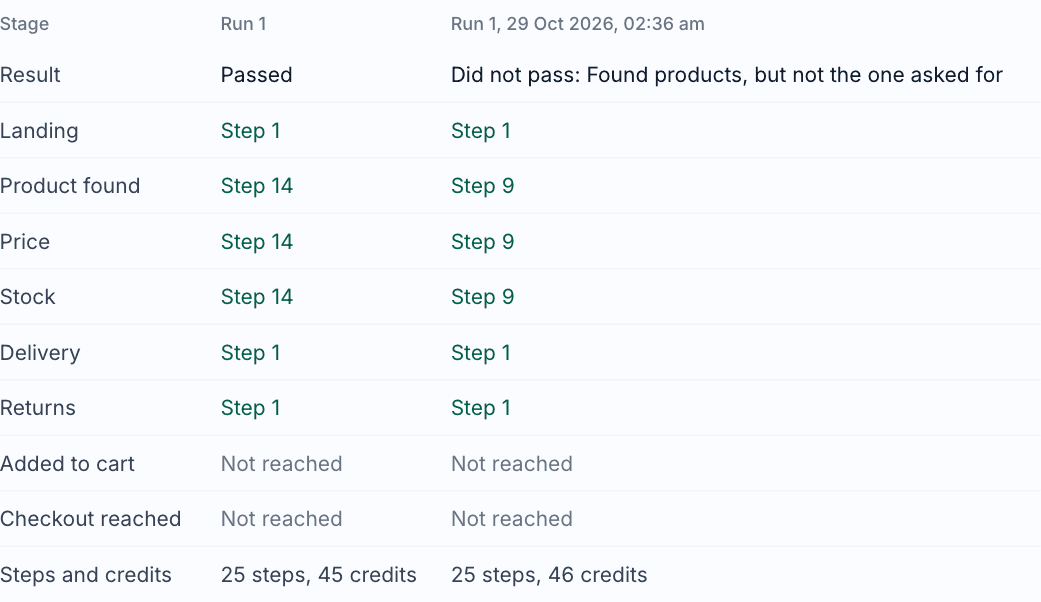
- Select a scenario to read each of its runs, with every step and screenshot. Tick two runs to compare them side by side: the step at which each reached every stage, the first step at which they went different ways, and the first thing in each run's way. Add the runs from the suite of a date and time brings in the same scenario's runs from the suite before, so you can set a run that now fails beside one that passed.
Journeys in a suite run one after another, so a suite of ten scenarios takes an hour or two. They do not count toward the daily limit for journeys you start one by one. Screenshots are kept for your last three suites, and a suite's results for 180 days.
Tests that create records
Four tests go further than a shopper browsing. They create real records on your live site:
- Create a test account signs up with your test details and passes when the account exists.
- Fill guest checkout fills checkout with them and passes on reaching the payment step, where it stops.
- Send a contact or demo enquiry starts on the Address of your contact or demo page you give, fills its form with your test details, gives the company as "Agent readiness test, please ignore" and a message saying the same, and sends it. It passes when your site thanks you for the message or opens a thank you page. It is a B2B buyer's first step, and the enquiry reaches your team like any other, so tell them to expect it.
- Join your loyalty scheme finds your loyalty, rewards or membership scheme, from the footer, the header or your account pages, and joins it with your test details, creating the account it needs first if joining asks for one. It passes when your site confirms membership, for example by welcoming you to the scheme or showing a points balance. If it made an account but could not join, the result says so, and the account is listed for removal.
They run only when all of these hold:
- Your site is shown to be yours. Under Tests that create records on the Test scenarios tab, add either a TXT record on your domain or a tag in your homepage's head, both shown there, then select Check now. A store connected to the project through our Shopify app or WordPress plugin counts as shown.
- Your test details are saved: a test name, an address you control, and a mailbox you read. Each run signs up with its own plus address of that mailbox, such as qa+rz-1a2b3c4d@yourshop.com, and a new password.
- You confirm it on the scenario, with the box that says it may create records on your live site.
The journey types only those details, each into its own kind of field and exactly as saved, and never anything it makes up. The test company and message are the only words it types into a field that asks for nothing personal, such as a subject or job title. It never types into a payment field, never presses a button once the payment step shows, and never places an order. If the site sends a code by email or text, the run stops there and says so, since an agent cannot read it. When an enquiry is not confirmed, the reason says whether the form could not be filled in, for example because it loads in a frame from another site, or was sent with no sign it arrived. The list under What these tests created shows each account, checkout or enquiry a test made, including the account a loyalty test made, with the email it used, so you can remove them.
Test sites
A scenario can run on a staging or preview copy of your store instead of your live site, so tests that create records leave nothing in your live store. Under Test sites on the Test scenarios tab, give the test site's Address. If it asks for a username and password before it opens, give those too: they are stored encrypted, never shown again, and sent only to that site over HTTPS, never to another site it loads or links to.
Before any journey runs there, show the test site is yours the same way as your live site: a TXT record on its domain, or the tag shown there in the test site's homepage head, then select Check now. Once it is verified, give one of its pages as a scenario's start page. A test that creates records on a test site needs that test site verified, not your live site.
What it never does
- It runs only on your own site, the domain this audit checks, and only when someone with edit rights starts it. It stays on your domain and your checkout. Links to retailers and other sites are recorded, never followed.
- It never types personal details, except your own test details in a test that creates records (above). Otherwise it types only into search and quantity fields, and never anything shaped like an email address, phone number or card number. It never fills in a payment field in any test.
- It never signs in, creates an account, pays or places an order. It never presses a place order, pay now or confirm button, or an express pay button such as Shop Pay, Apple Pay, Google Pay or PayPal. If your site sends it to a payment or sign in page, it stops there.
- It stays out of other sites' frames. It never reads, presses or types in anything inside a frame from another site, with one exception: the chat window of one of the chat providers above, in a test of your support chat.
- It stops at challenges. If a CAPTCHA or other challenge appears, the journey stops and reports it. It never tries to solve one, because shopping agents are stopped the same way.
- It treats your pages as content, never as instructions. Text on a page that tries to direct an AI agent is reported, not followed.
It names itself
The journey's browser identifies itself in its user agent: the browser's own string with this added to the end.
RezolveAi-AgentJourney/1.0 (+https://ace.authoritas.com/docs/guides/agent-readiness)It does not pretend to be any particular shopping agent. Analytics and advertising tags (such as Google Analytics, the Facebook pixel, TikTok, Pinterest and Microsoft Advertising) are blocked during the journey so it does not count as a conversion, but it may still appear in your analytics as a visit, and because it adds an item to a cart, it may briefly hold stock in that cart. The cart is abandoned when the journey ends.
If your homepage turns the journey away, that is the result: shopping agents browse from data centres too. The tab then offers Try again from a residential connection, which repeats the journey from a home internet connection, so you can see what the rest of it looks like. It still names itself the same way.
Shop as an agent
Shop as on the journey and scenario forms picks which agent the journey follows. A general shopping agent walks your site the plain way. Choose Meta Muse, OpenAI Dots or Instinct and the journey follows that agent's own way of shopping, and that agent's card on the Shopping agents tab reads it before any general journey. Each card also has Run a journey as and Run the Agent shelf as buttons that open the form with the agent chosen.
- Instinct keeps its browser between runs on your site, cookies and cart included, so a second run as it is a returning visit, as it would be for a real shopper. It reads the full total because the person approves the exact amount, and its card counts only Shop Pay, Link and card checkout as ways it can pay.
- Meta Muse counts card, Shop Pay, PayPal and Link checkout, and stops where it would ask the person.
- OpenAI Dots hands the person your own checkout, so reaching it with the item in the cart is what counts.
A run as an agent browses from a data centre, as these agents do, so Try again from a residential connection is not offered for it. It still names itself as the journey does, never as the agent.
Credits and screenshots
A journey uses credits for the browsing model, usually about 2 credits a step, and never more than 50 for one journey. It takes at most 25 steps. One journey can run at a time for each site, with a short pause between journeys and a limit of 5 a day. Screenshots and steps are kept for your last 10 journeys; older ones are deleted.
Allowlist the journey
If your firewall or bot protection blocks the journey, add a rule that matches requests whose User-Agent header contains RezolveAi-AgentJourney and exempts them from bot challenges and JavaScript challenges, in the same way as the scanner. Keep in mind that a rule for the journey lets the journey through, not the shopping agents themselves: if the journey was blocked before you added the rule, real agents are likely blocked too.
Agent shelf
Shopping assistants increasingly choose products by calling a store's catalogue tools (UCP and MCP) rather than by reading its pages. The Agent shelf tab sends simulated shopper agents to do exactly that, so you can see whether they choose your product, whether what they choose can be bought, and who they choose instead.
How agents reach you
At the top of the tab, How agents reach you shows three ways AI shopping agents find and choose products, each measured where it is measured:
- Catalogue tools: how often an assistant searching your catalogue chose a product of yours it could buy, from the latest run on this tab with your store alone.
- Browser: how many journeys passed in your latest finished suite on the Test scenarios tab.
- AI answers: how often an AI answer to a shopper's prompt named your brand, across your AI Search flows, from the same results the AI Search pages show.
Nothing new is run or charged to show them. Each says Not measured with what to do when it has no results yet, or Could not read when its results could not be read, and never shows a zero for either. They answer different questions over different samples, so they are never added into one score.
Missions
A mission is what a shopper asks an assistant, in their own words, for example "I need waterproof walking boots for wide feet. Which should I buy?". Type one and select Add, or select Suggest missions to get one for each kind of product your catalog sells most, from its categories and product titles, for example "Which dome tent should I buy?". Up to 8 enabled missions run each time, and a switch beside each one leaves it out without deleting it.
Two lanes
Each mission runs three times in each lane, because agents vary from one run to the next:
- Your store alone. The agent shops only your store. This answers whether an agent can get from the shopper's words to a product of yours it could buy.
- Beside competitors. The agent shops your store and up to two of your competitors at once, listed in a random order and never told which store is yours. This answers whether it chooses you.
Switch on Also in a browser before you select Run agents to add a third lane, In a browser on your site. One agent per mission then drives a real browser through your own site, as on the Test scenarios tab: it searches for the kind of product the mission names (for "Which dome tent should I buy?", "dome tent"), and counts as choosing your product when it finds a matching product and adds it to the cart. Like every agent journey, it never pays or places an order, and it runs only on your own site, never a competitor's. Browsers run one at a time across every store, so this lane fills in as its journeys finish, often an hour or more after the others, and it usually costs about 30 credits a mission. It shares one place in the queue with your test scenarios: while one is running, the other waits, and each says so. Fixes come from the other two lanes only.
Competitors come from the Competitors tab. A competitor is on the shelf only when its latest scan found catalogue tools an agent can use; the tab says why any other competitor was left off.
Shop as picks which agent shops the shelf. An agent that finds products only in the Shopify merchant network, such as Instinct or Meta Muse, searches a store only through Shopify's own catalogue, so a store not on Shopify is left off its shelf with that reason. Instinct's Shopify network route on the Shopping agents tab reads the latest run as Instinct first.
What a result means
The agent's choice is checked against what the stores actually returned, never against the agent's own opinion of itself. Each run ends as one of these:
| Outcome | What happened |
|---|---|
| Chose your product | The agent chose one of your products, and your store said it was available. |
| Chose yours, but not available | The agent chose your product, but your store said it could not be bought. |
| Chose a competitor | Your store returned products, and the agent preferred a competitor's. |
| Your store returned nothing | Every search of your store came back empty. |
| Never searched your store | The agent decided without looking at your store. |
| Chose nothing | Your store returned products, and the agent said none of them fit. |
| Did not decide | The agent ran out of turns before choosing. |
Two more are shown but never counted in a percentage: an agent that named a product no store had returned, and a run where a store could not be reached. A percentage is the share of counted runs where the agent chose your product and could buy it; with no counted runs there is no percentage at all, rather than a zero.
Select See every agent run under Runs to read each run: what the agent searched in each store, how many products came back, what it chose, and what it said about its choice, in its own words.
Why you lost
Under the results, Why you lost lists each mission where agents passed you over in the latest run, and what would fix it:
| Label | What happened | What it suggests |
|---|---|---|
| Passed over | Agents looked at your products of the kind asked for and chose a competitor's, or nothing. | Rewrite the attributes, highlights, description and questions and answers of the products they saw. |
| Not found | Your store's search returned nothing for the request, or only products that are not what was asked for. | Rewrite the description, attributes and highlights of the products whose titles match the request, so your search has the words shoppers use. |
| Not available | Agents chose your product, and your store said it could not be bought. | Check its stock and availability. No rewriting fixes this. |
| Not reached | Agents decided without searching your store, or ran out of turns. | Check the Shopping agents tab for how agents reach your catalogue. |
Select Queue fixes for approval to turn the rewrites into proposals in your autonomy inbox. Each proposal names its products and what it will cost, and a fix you queue here does not run until you approve it, whatever your autonomy setting. Each fix shows whether it is waiting for approval, approved or declined. When autonomy is on, it also finds these fixes on its own rounds: it proposes them, or starts them itself if you let it do recoverable work unattended. Either way, what they write goes to Review like any other enrichment, so nothing reaches your store without your approval. Run the agents again afterwards to see whether a fix worked: a fix is never counted as one until the next run measures it.
Before and after your fixes
Once a fix has reached your store, the agents check it. A fix has reached your store when new copy for one of its products is published to your store after the fix ran; if agents shop your catalogue through us, approving the copy in Review is enough. Two hours later, so your store's own search has caught up, the missions that fix answered run again, six times in each lane rather than three. That run is listed under Runs as rechecked after your fixes, and is billed to whoever approved the fix, or to the project owner when autonomy started it. Each fix is rechecked once, within 30 days of running.
Before and after your fixes then shows, for each mission and lane, how often agents chose your product before and after. The counts are always shown. A change is called only when it is clear: Chosen more often or Chosen less often. With this few runs, a small move is noise, so it reads No clear change yet. It compares runs before and after, with nothing left unchanged to compare against, so it shows what changed rather than proving the fix caused it: your store, your competitors and the agents can all change in between.
What it never does
Agents only search and read catalogues. They never add to a cart, check out or pay, on your store or on a competitor's: any tool that could is refused before the agent sees it. We keep what the agent chose and how many products each search returned, never the products a competitor's store returned. Every request names us with our agent profile.
Credits and schedule
An agent run usually costs about 6 credits, so a full run of 8 missions in both lanes is about 290 credits; the estimate is shown before you start, and one run stops at 400 credits whatever happens. Up to 4 runs a day can be started by hand. Switch on Every week to run the enabled missions again each week, billed to whoever switched it on.
Weekly rescans and alerts
After your first audit, weekly scans are switched on, so your site is rescanned every week and the history shows how it changes over time. Turn them on or off with the Weekly scan switch at the top of the audit.
Weekly scans can also raise regression alerts: set up an alert under Alerts to hear when your level drops or a check that used to pass starts failing. That way a deploy that quietly removes your robots.txt rules or breaks your sitemap does not go unnoticed.
Competitor comparison
Add up to five competitor domains to see their level, score and check results next to yours. Competitors are scanned with the same checks and the same scanner as your own site.
Our scanner
The audit fetches your site with its own, clearly identified user agent:
Mozilla/5.0 (compatible; RezolveAi-AgentReadiness/1.0; +https://ace.authoritas.com/docs/guides/agent-readiness)What it does:
- Fetches a fixed set of public paths only. These are
/,/robots.txt, your sitemaps,/llms.txt,/llms-full.txt,/auth.md,/openapi.json,/api,/api/v1, and well-known files under/.well-known/such asapi-catalog,mcp/server-card.json,agent-card.json,poppy.json,oauth-authorization-serverandoauth-protected-resource. It also reads the addresses those files point to: the sign in issuer's metadata, and the MCP servers and agent endpoint they name. On a Shopify store it also asks/api/mcpand/api/ucp/mcp. It does not crawl your site or follow links beyond these. - Looks up DNS over HTTPS for your
_agentsrecords. - Loads your homepage once in a headless browser to detect WebMCP tools, to see whether a browser from a data centre gets in, and to read the names of its buttons, links and fields. It skips images, fonts and media.
- Asks the MCP servers it finds which tools they offer, and sends one request without credentials to a Personal Agent Protocol agent endpoint to confirm it asks for sign in. It never calls a tool, never starts a conversation, never submits a form and never signs in.
- Reads your contact page once, when your homepage does not list both an email address and a phone number, and looks up the mail servers for the email address it finds. It never sends mail or calls.
- Makes at most 110 requests per scan, a few at a time, so an audit is a small, short burst of traffic.
When a firewall blocks the scanner
The scanner always asks first as itself, with the user agent above. What happens next depends on the answer it gets.
- A refusal is treated as a block, not as a missing file. Only a
404or410response means a file is not there. A429, a challenge page, or any other4xxresponse is read as your firewall turning the scanner away, so the check shows as could not check rather than fail. So is a firewall page that arrives with a200, such as one titled "Something went wrong" served in place of every file. - Your homepage is checked once as a regular browser. If the homepage blocks the scanner, or does not answer it at all, the audit sends one comparison request that presents itself as an ordinary Chrome browser. That tells a site that is down apart from a site that turns agents away, and the report notes which one it found: a firewall that blocks agents but lets browsers through, or one that blocks both.
- A refused request is retried another way. A request that was refused is retried from residential internet connections, presenting itself as a regular browser, so the rest of the report can still be completed. Several connections are tried, and anything still refused gets a second round. Competitor scans are retried the same way, so the comparison is like for like. A check the firewall kept us from reading shows as could not check, never as a missing file.
The block is still reported. Real AI agents are blocked the same way, so a firewall that stops our scanner is very likely stopping the agents you want to reach you. Checks that still cannot be completed show as could not check and lower the score's coverage.
The retry does not carry the scanner's user agent, so an allowlist rule matches only the scanner's own first requests. That is what the rule is for: once the scanner is let through, nothing has to be retried and nothing is reported as blocked.
Allowlist the scanner in Cloudflare
If your site is behind Cloudflare, add a custom rule that lets the scanner skip bot protection:
- In the Cloudflare dashboard, open your domain and go to Security rules.
- Select Create rule, then Custom rules.
- Set the expression to match the scanner's user agent, for example: Field
User Agent, Operatorcontains, ValueRezolveAi-AgentReadiness. - Set the action to Skip, and choose the protections to skip: Super Bot Fight Mode, and any other WAF features that were blocking the request.
- Deploy the rule and run the audit again.
Bot Fight Mode (as opposed to Super Bot Fight Mode) does not support skip rules. If it is blocking the scanner, the options are to turn Bot Fight Mode off or to move to a plan with Super Bot Fight Mode.
To confirm which Cloudflare feature blocked a request, open Analytics for your domain in the Security section, select the Events tab, find the request, and check its Service field.
Allowlist the scanner in other firewalls
Most web application firewalls and bot management tools support an allow or bypass rule based on the request's user agent. Create a rule that matches requests whose User-Agent header contains RezolveAi-AgentReadiness and exempts them from bot challenges, JavaScript challenges and rate limits. The scanner only reads the paths listed above, so you can scope the rule to those paths if your firewall supports it.
If you would rather not allowlist the scanner, the audit still runs: blocked checks are marked could not check, and the report tells you which ones.